
From Content Credentials to AI licensing and attribution
At the IPTCIPTC: The news-industry body that sets photo metadata fields and vocabularies, including the digital source type values C2PA uses. Photo MetadataMetadata: Data stored beside the content in a file, such as author, camera or date. Many tools strip it when they copy or upload a file. Conference, Erik Svilich followed one signed WordPress article into an AI answer. The demo showed how the label's rights terms and credit could support attribution and a usage-based payment.

- Event
- IPTC Photo Metadata Conference
- When and where
- September 2026, IPTC
- Speaker
- Erik Svilich, founder and CEO of Encypher.
- Length
- 10 minutes 21 seconds, with a full transcript below.
Publish once, with credit and terms
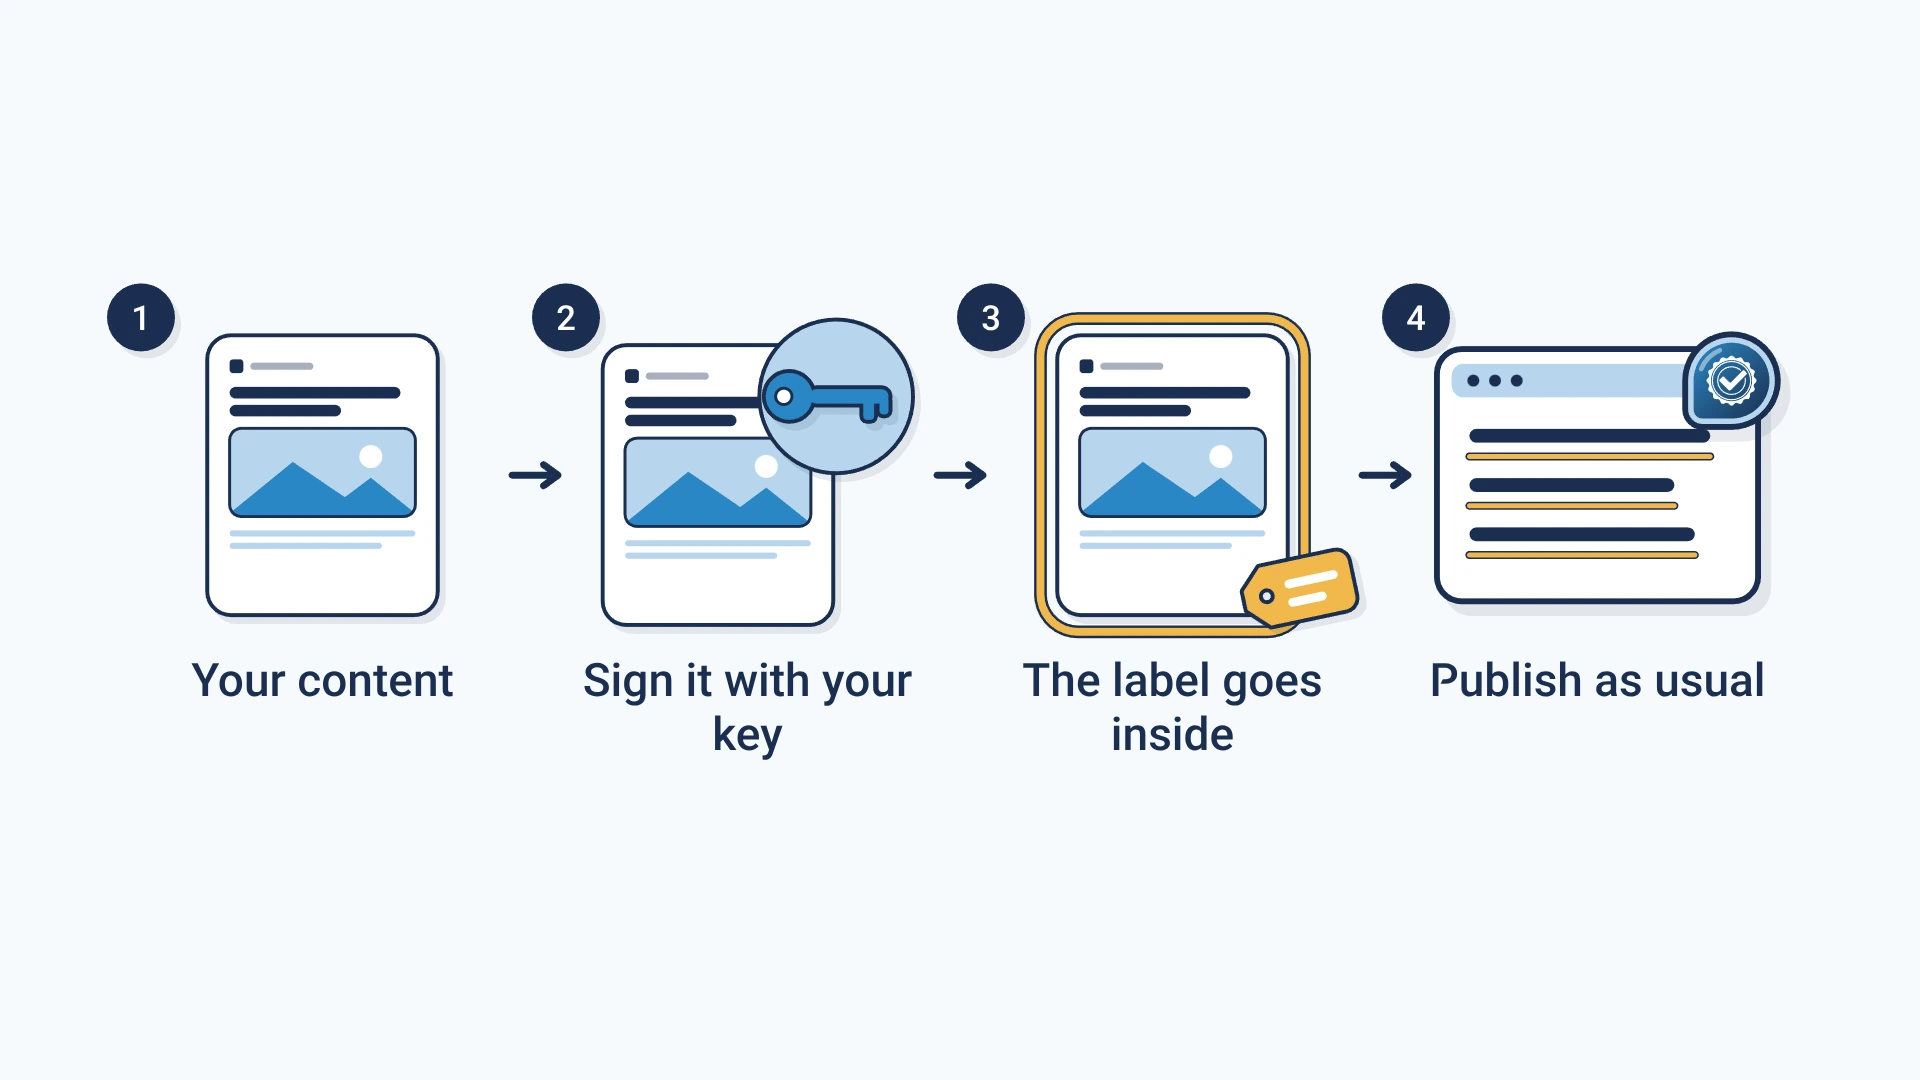
The demo article mixes text, images, video and audio. Erik adds editorial details and picks a rights policy written in ODRLODRL: Open Digital Rights Language: a W3C format for writing usage terms that software can read., a W3C language for usage terms. The plugin signs each block. It works out each file's hashHash: A short fingerprint of exact bytes. Any change, even one character, gives a completely different hash. on the site, so large files never travel to the signing server.
The signed result shows the publisher, the Content CredentialsContent Credentials: The public name for a C2PA label, often shown as a small CR icon that opens who signed the content and what they declared., the editorial details and the terms for AI use, in a form machines can read.
Follow the story into an AI answer
A Usage Lab checks four uses against the sample terms: search, training, sharing and research. Some are allowed with duties. Others are not.
Then a live question pulls in signed items. Not every item that shapes an answer shows up in it. That is why each step is worth recording on its own.
From use to credit and payment
Erik showed a made-up bill: five items used at $0.25 each comes to $1.25. No real payment was made. He closed on what the same record could do next. It could help AI quote a source word for word and credit it. It could also show ad buyers which publisher a page came from.
Speakers, chapters and transcript
Show the technical detailEvery word of the recording, with chapter times.
Speakers
- Erik Svilich (Founder and CEO of Encypher; author of the C2PA unstructured text specification)
Chapters
- 0:00 Introduction: metadata and machine permissions
- 1:09 WordPress demo and mixed-media publishing
- 1:32 IPTC metadata and ODRL licensing
- 2:15 Local hashing and automated signing
- 3:04 Inspecting provenance in the media library
- 3:45 Content Credentials, identity, and AI-use signals
- 4:55 Machine-readable rights and provenance
- 5:49 Usage Lab: search, training, distribution, and research
- 6:45 Running a live AI query
- 7:08 Retrieval, grounding, citations, and display
- 8:09 Hypothetical usage-based settlement
- 8:25 Licensing, attribution, and accurate quotations
- 9:16 Advertising and verified inventory
- 9:54 Closing: connecting creators and consumers
Transcript
This transcript is based on the recording's subtitles, grouped into paragraphs with obvious name and terminology errors corrected. It may contain mistakes, including in timing and speaker labels. Statements about product capabilities, commercial results and legal matters are the speaker's remarks at the time of the presentation. The recording is the source of record.
- Moderator
- So, Erik, I will start off your timer now.
- Erik Svilich
- Yeah, thank you. Hey, everybody. I'm Erik Svilich, founder and CEO of Encypher. Some of you also might know me due to my C2PA work. I authored C2PA's unstructured text specification. I'm pretty deeply involved in those. And what I really wanted to talk about here, this is part of our WordPress plugin that we have.
- Erik Svilich
- But really, for decades, this room and this group of people here has taught machines what the news is. And nobody has really taught them what the machines can do with it. And like this gap that we see today is why a lot of news businesses are bleeding. There's essentially, from our perspective, no mark and no embedded license means no consent. And that's still up for debate. And I'm not going to get too much into that today, but that's more of our perspective. And so we're really focused on this creator to consumer workflow, which is kind of similar from glass to glass, but a little bit different. And I'll tell you why.
- Erik Svilich
- So we have a WordPress plugin available today on our website. It's completely free that can sign content, scan your media library for provenance, a whole bunch of fancy settings. I'm not going to get into it. We're just going to go into a sample draft piece of content today. And we have an article here with text, images, video, audio.
- Erik Svilich
- And for example, if we click here, there are some information, editorial information that we can put in here. And this uses ninjs as well, the IPTC photo metadata standard to put in additional provenance information, editorial information that is also linked to the C2PA manifest. And we also have a license and rights link where you can select from a variety of license and rights schemas, which is actually based off of the W3C ODRL standard.
- Erik Svilich
- And you can edit all of this in the Encypher dashboard. It pulls directly from there. So you can kind of build whatever type of licensing schema that you want.
- Erik Svilich
- So every single block here will get automatically queued for signing and publishing on your website. We have a feature, everything gets hashed locally, so you're not sending huge media files back and forth between our servers and yours. And it is embedding this license and rights information, editorial metadata, and C2PA manifest data as we speak into the images, video, audio, and text on the page. So it doesn't change your editorial workflow very much.
- Erik Svilich
- You don't really need to know what C2PA is or what all these different metadata technical standards are. It's just handled all for you. It can take a second because it's hashing every single thing on the page, sending it to the server, and then returning the signed logic.
- Erik Svilich
- One thing that I should mention as well is on the media library as well, kind of similar to the Adobe tool, you can inspect the saved provenance right there and then. And essentially, whenever you upload an asset, you know, it's user-generated content or stuff like this.
- Erik Svilich
- For some reason, this is taking a very long time to sign. We're just going to pop over to one of the pre-signed samples because it's taking a long time. We're going to view this. You can check whether that uploaded content has provenance or not.
- Erik Svilich
- So I'm going to click this little icon, which is how we put on different media assets to display that there's provenance information here. We can see that it was published by Encypher Corporation from our trust root. We're a certificate authority and timestamp authority on the C2PA trust list, as well as a conformant generator. We actually handle 20 products for the conformance program right now, but we actually handle over 80 formats for signing.
- Erik Svilich
- We also have all this technical evidence here, just for the demo purposes here, where we can show you that we support CAWG identity 1.2. It's rooted to our own trust list that we created for people that aren't part of the IPTC world, people doing AI compliance with these type of things. But we also support the IPTC trust list and CAWG identity certificates, along with some more information around the IPTC photo metadata, what's represented within that data, as well as CAWG AI-use signals, whether training, inference, or mining is allowed or not, and the ODRL rights engine information as well.
- Erik Svilich
- And if you really want to see, for example, what that looks like, it looks like this. I assume you guys aren't machines, so it's a little bit difficult to read, but this is essentially one object that the machine can read that handles the ninjs metadata. It handles C2PA and CAWG assertion metadata, any watermarks that are included, because we also support watermarks across every format that we sign.
- Erik Svilich
- So that any consumer of your content, whether it is directly on your web page, like shown here, or if it is, let's say, goes onto the internet somewhere else and still carries that metadata, can show that this piece of content was from you or your organization and has these licenses and rights associated with it. So again, a little bit why is this important, right? So we have this verified content. We were just shown earlier that this builds trust with users. You can change how much information showed to users.
- Erik Svilich
- We have this usage lab that we've been working with the SPUR Coalition on for their open attribution, open attribution standard. And for example, we have a couple of scenarios here. So we have a US search agent, a US training model, distribution agent, and EU research crawler. And this all pulls from the cryptographic metadata that's within the published assets here.
- Erik Svilich
- So for example, the US search agent is permitted with a duty, perhaps because every time they access it from your website, they may have to pay a fee. So for example, this scenario is it's using it for RAG retrieval. There's these ODRL scopes, for example. And if we change this to a training model, it's prohibited. And if we train this to a distribution agent, it's permitted with duty. So they might need to pay. If we change this to a research crawler from the EU, it's prohibited based off of your own ODRL schema.
- Erik Svilich
- So if I ask, how may an AI system use this package, what duties to apply, and how is ODRL involved? Just for fun, this is going to run a real-time search query and pull from the information on the website. This might be a little bit difficult to read here. I'm going to blow this up really quick.
- Erik Svilich
- And for example, we see here that eight things were retrieved by the licensing gateway. Five were grounded as part of the response here. Five items were grounded in the response. So they're not displayed to the user, but they inform the response. And four were cited and four were displayed. So for example, if we click on one of these, we can see and verify the provenance behind that.
- Erik Svilich
- For multiple of these sections, these are all different articles that were signed with Provenance with the WordPress plugin. And it even pulled an image with metadata and rights associated with it as part of this response. So essentially, we're trying to tie and what IPTC has done really, really well with what is this news object, right, with the metadata, tie that and have it survive and link it to the C2PA metadata that says, I'm this organization, I put this content out in the world, here's what you can do with it, type of scenario, right?
- Erik Svilich
- And for example, this also gets into settlement, right? So depending on how much stuff was grounded, in this case, 25 cents per grounding, we are then owed $1.25 in this hypothetical scenario.
- Erik Svilich
- And so that brings me to Provenance is a really cool thing for building trust with users. It's very impactful, as was shown before, but there's actually a really awesome business use case for using metadata, which is into AI licensing and attribution. You know, there were some lawsuits in Germany over this as well. This can even help the AI companies that you may have an agreement with actually accurately quote you versus just paraphrase you. Because if your brand is being represented in an AI response, I am sure you would want to verify that it is an exact quote unless you're okay with paraphrasing, right?
- Erik Svilich
- Because we all know AI hallucinates and having a way to cryptographically verify that transaction can really make or break trust with users and even help with liability.
- Erik Svilich
- We also work with advertisers and brands as well, where we have with early partners essentially some new ad tech rails where we can get you up to an extra about $10 to $15 per every hundred dollars of ad spend using our ad tech ecosystem, using Provenance as essentially the way to transact and produce verified inventory.
- Erik Svilich
- So I believe I'm nearing up on my time. Please let me know if I'm close. But essentially, I just five seconds.
- Moderator
- You got five seconds. Quick. Go, go, go.
- Erik Svilich
- Okay.
- Erik Svilich
- So essentially, we want to bridge the gap between those that are creating content and those that are consuming content, whether they're humans or machines, and make sure that your license and rights are represented across the open internet and when it goes into an AI system. So thank you very much.
Create. Mark. Endure.
Sign a sample story with your terms and read back what its label says.